


Deterministic and verifiable LLM inference



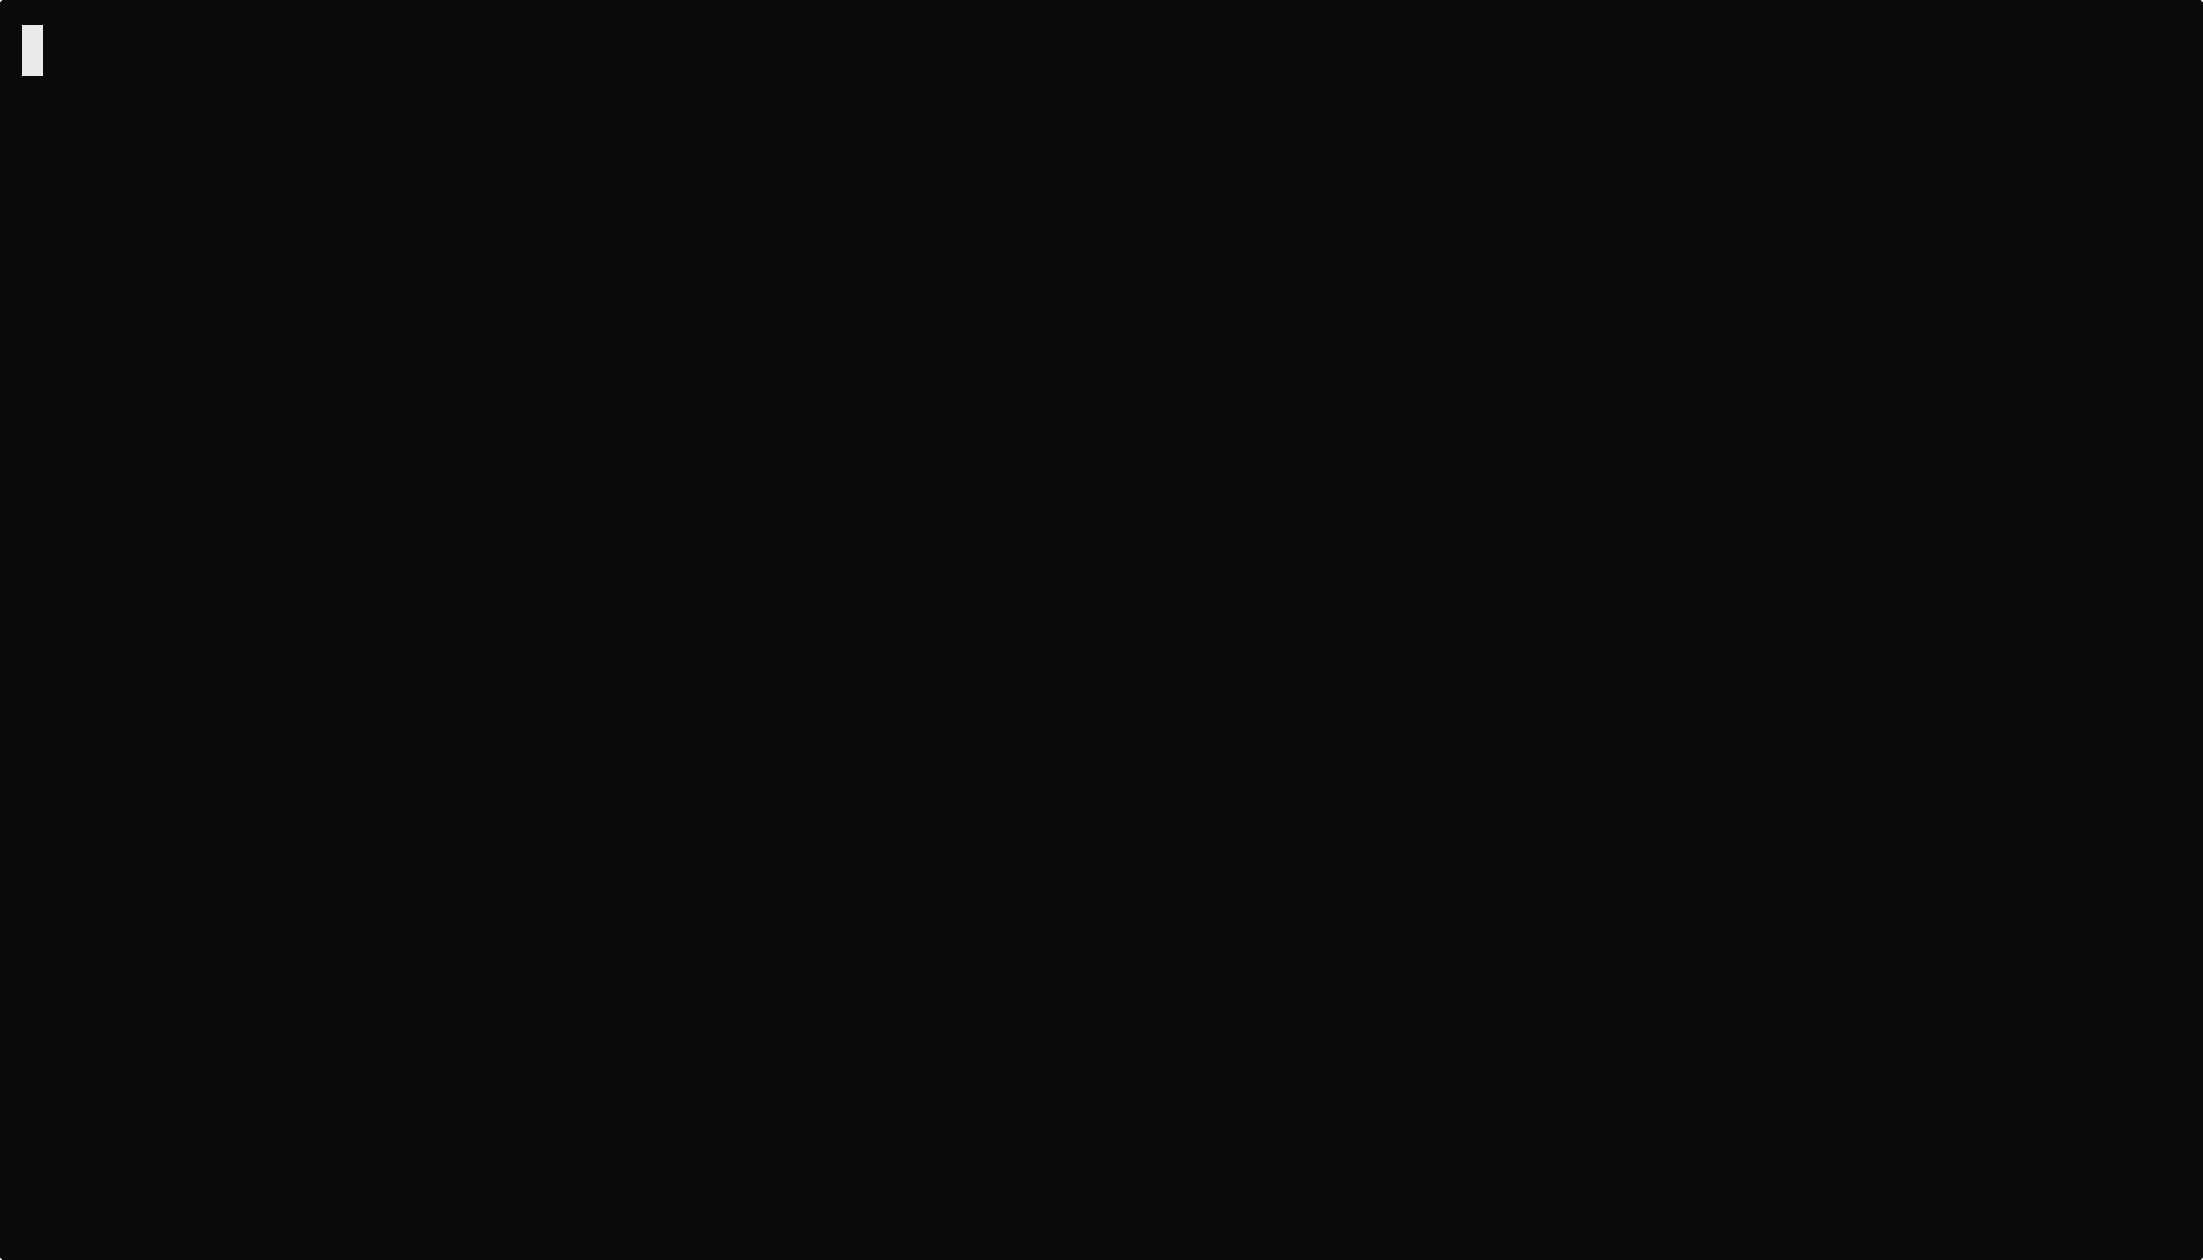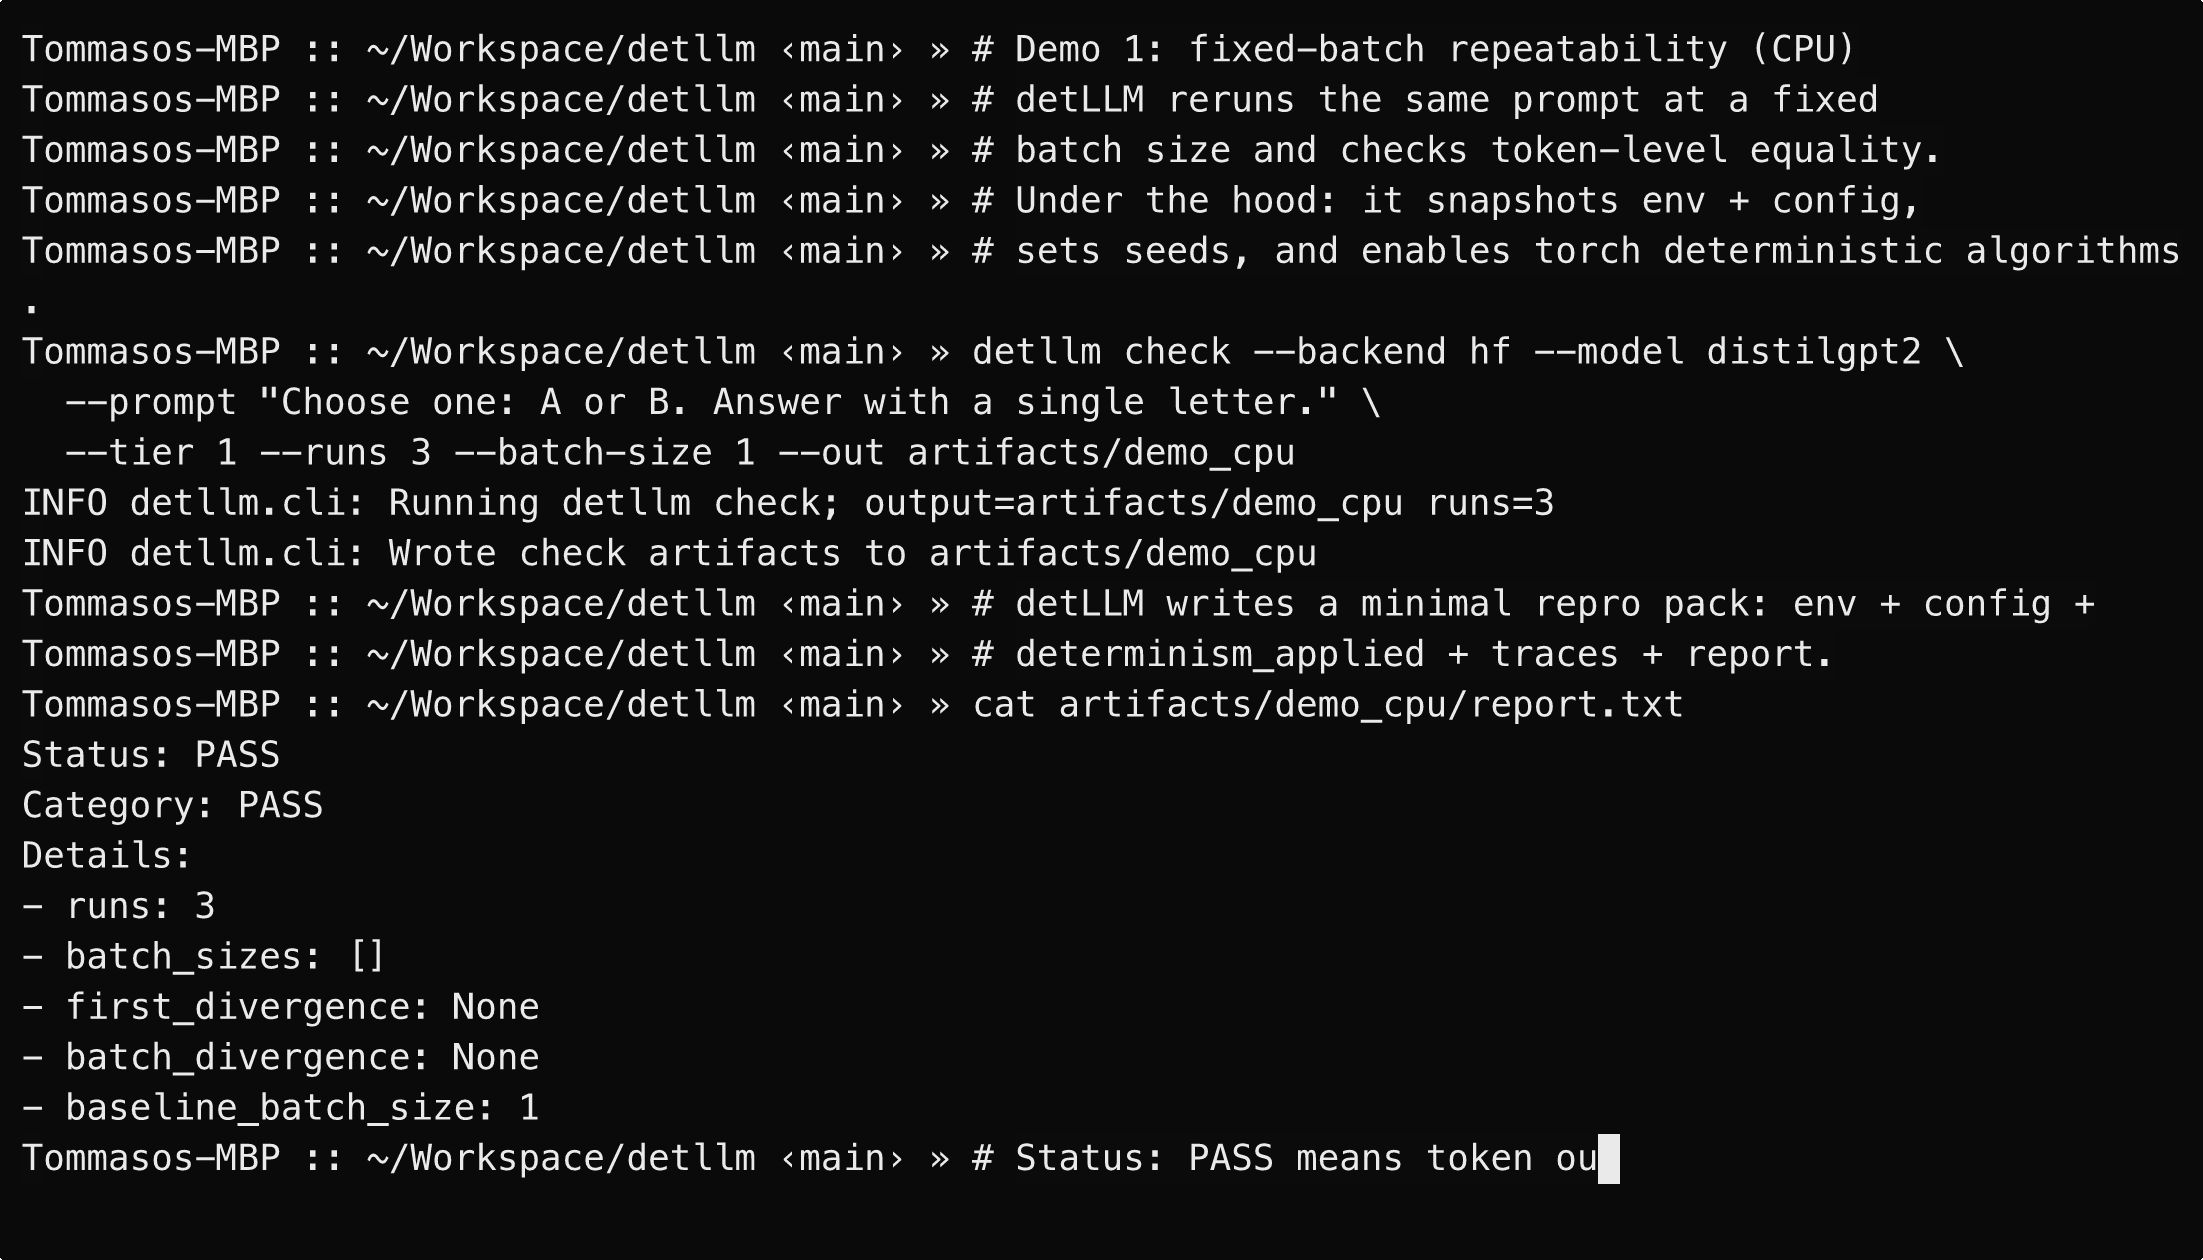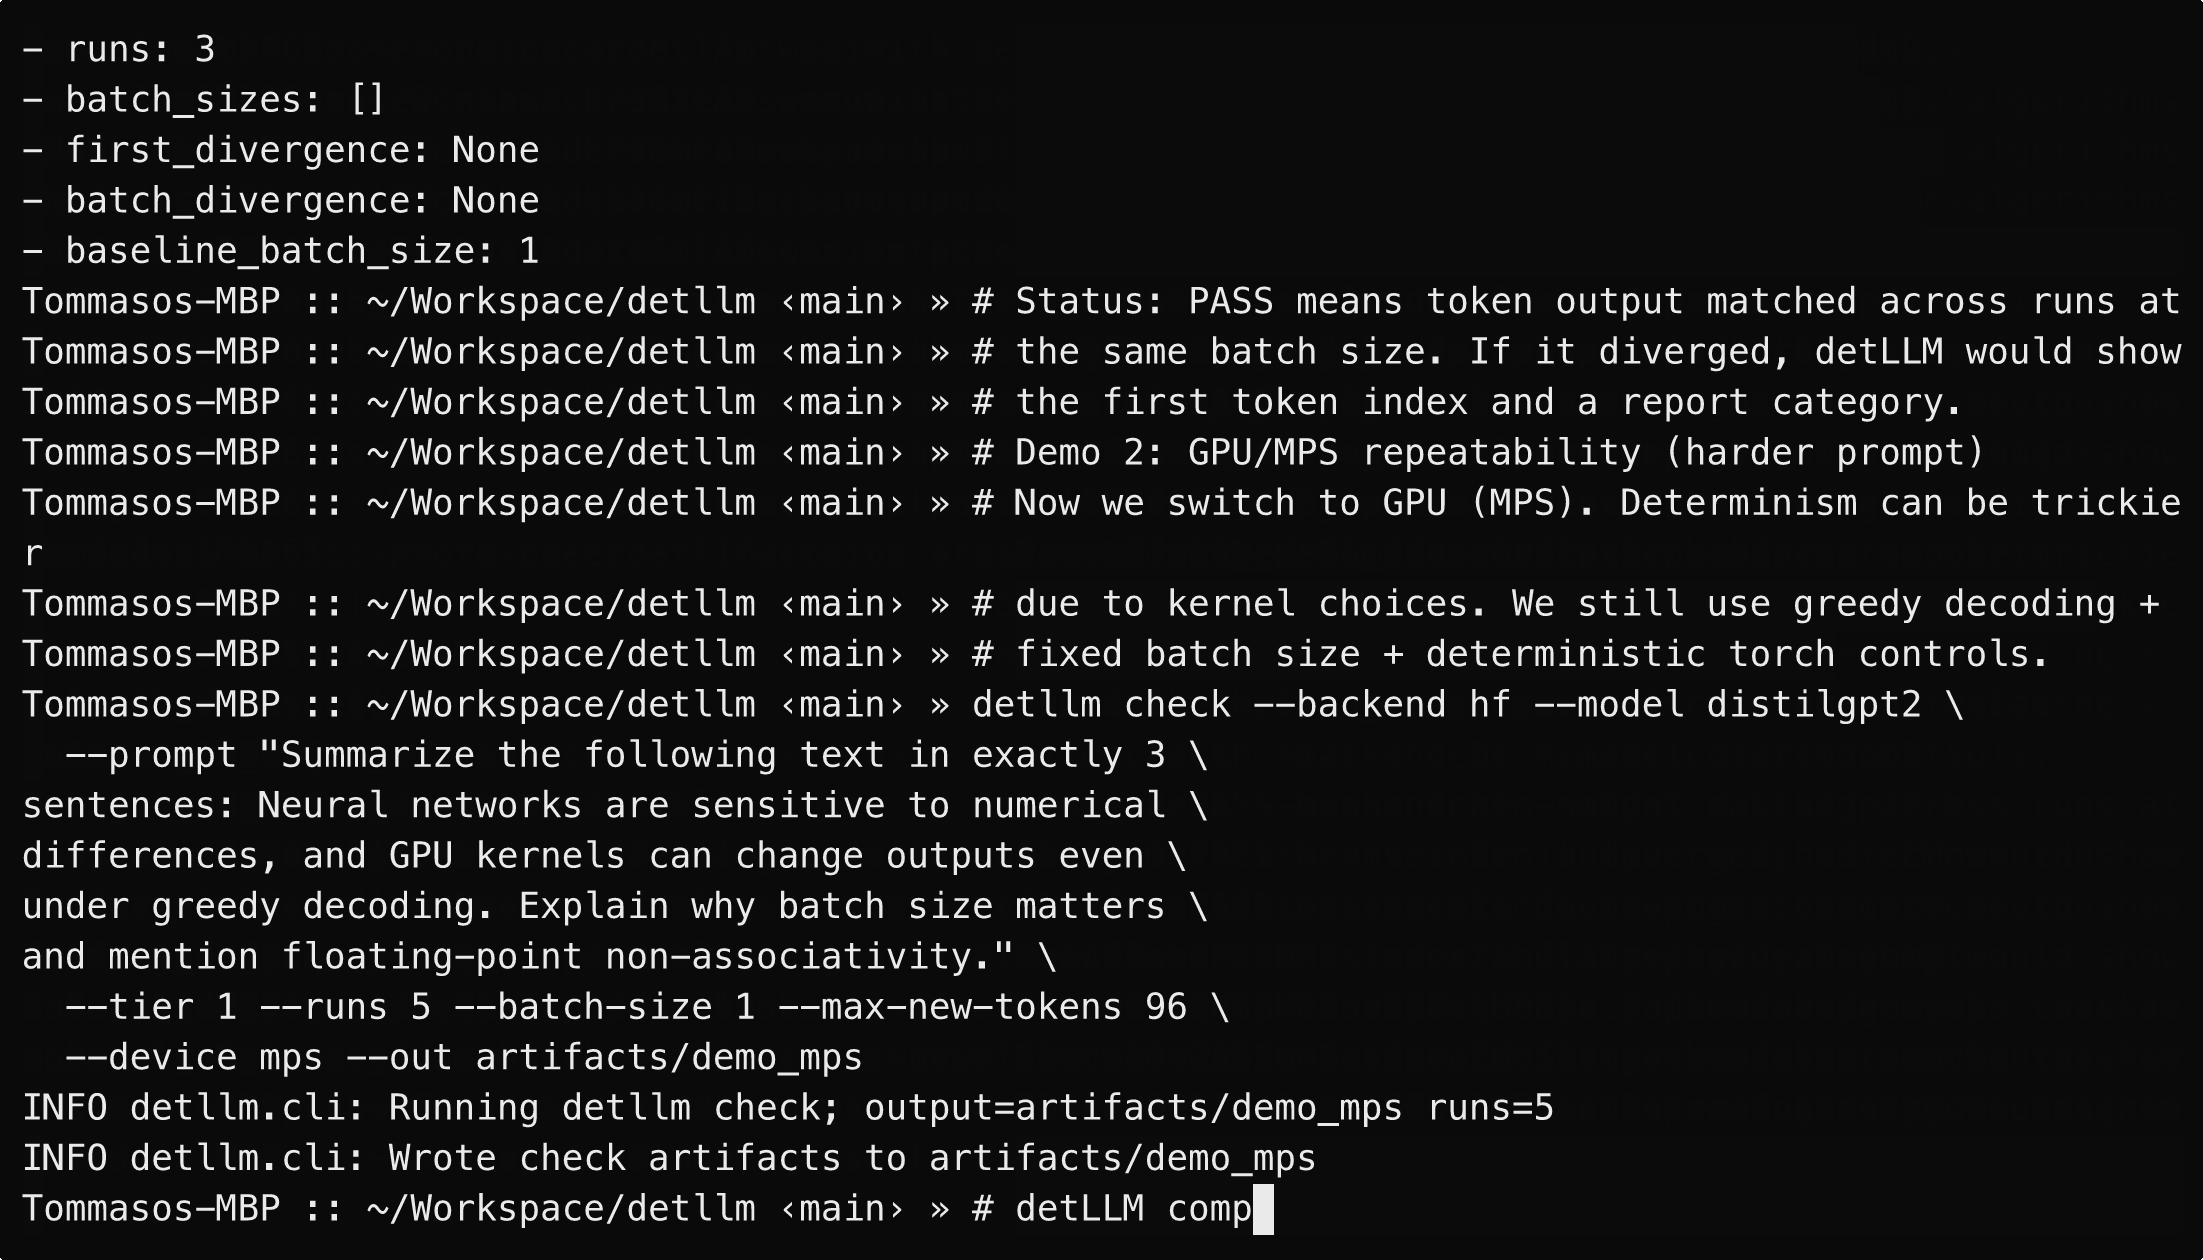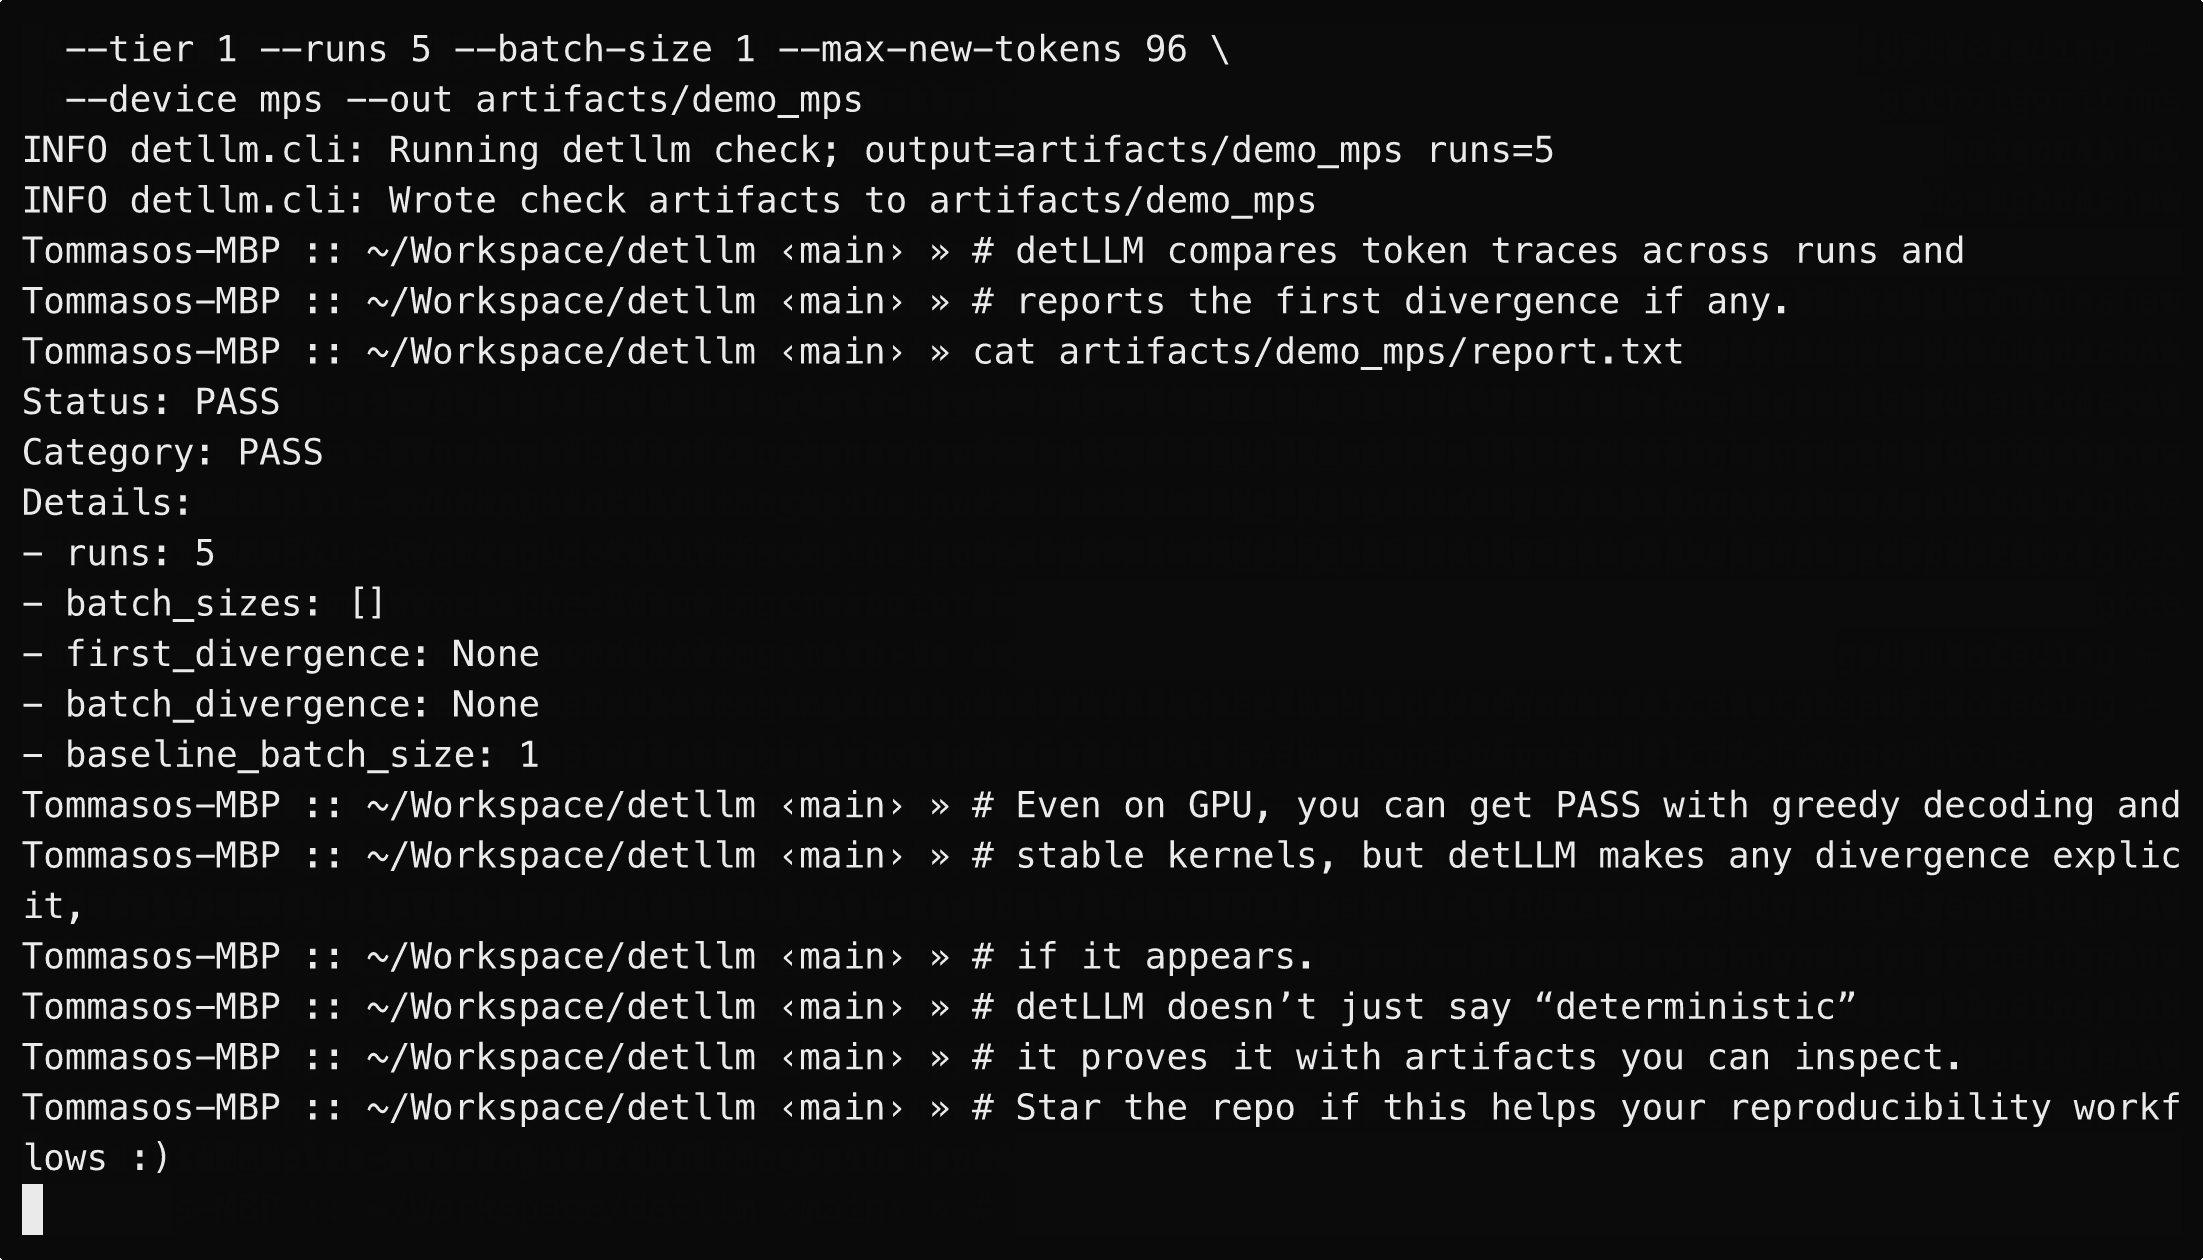
detLLM verifies reproducibility for LLM inference and produces a minimal repro pack when outputs diverge. It measures run-to-run variance and batch-size variance, and reports results with explicit, capability-gated guarantees (only claimed when the backend can actually enforce them).
pip install detllm
detllm init --out .
detllm doctor
detllm profile run quick_check --dry-run
Note: some shells (like zsh) require quotes when installing extras, e.g. pip install 'detllm[test,hf]'.
See docs/examples.md for runnable local workflows covering
check, diagnose, replay, phase, analyze, and recommend.
See docs/verification.md for the full local verification procedure and expected outputs.
- Tier 0: artifacts + deterministic diff/report (no equality guarantees)
- Tier 1: repeatability across runs for a fixed batch size
- Tier 2: Tier 1 + score/logprob equality (capability-gated)
Tier 1 guarantees repeatability only for a fixed batch size; batch invariance is measured separately.
Tier 2 scores are captured when the backend supports stable score/logprob output. See docs/verification.md for how to verify scores appear in traces.
Each run writes an artifacts/<run_id>/ folder:
env.jsonrun_config.jsondeterminism_applied.jsontrace.jsonlreport.json+report.txtdiffs/first_divergence.json
from detllm import check, run

run(
    backend="hf",
    model="distilgpt2",
    prompts=["Hello"],
    tier=1,
    out_dir="artifacts/run1",
)

report = check(
    backend="hf",
    model="distilgpt2",
    prompts=["Hello"],
    runs=3,
    batch_size=1,
    out_dir="artifacts/check1",
)

print(report.status, report.category)detllm envdetllm rundetllm checkdetllm diffdetllm reportdetllm initdetllm doctordetllm inspectdetllm profiledetllm diagnosedetllm replaydetllm phasedetllm analyzedetllm recommend
detllm diagnose --in artifacts/check1 ranks likely causes for a repro pack and
writes diagnosis.json + diagnosis.txt.
detllm replay --in artifacts/check1 --probe autoThe replay command runs targeted local probes when prompt text was captured with
--include-token-text.
detllm phase sweeps controlled inference variables such as batch_size,
dtype, and max_new_tokens, then writes phase_diagram.json,
phase_diagram.csv, and phase_diagram.txt with stable/fragile/unstable
regions.
detllm analyze --in artifacts/phase/distilgpt2 consumes a phase diagram and
writes analysis.json, analysis.csv, and analysis.txt with Wilson
confidence intervals, a reproducibility risk score, and recommended next
experiments.
detllm recommend --in artifacts/phase/distilgpt2 ranks follow-up cells to run
next and writes experiment_plan.json, experiment_plan.csv, and
experiment_plan.txt. V1 is recommend-only: it never loads a model or runs
inference.
detllm init writes a starter detllm.config.json and prompts.jsonl.
detllm doctor checks local dependencies without downloading models.
detllm inspect --in <artifact_dir> summarizes generated artifacts, and
detllm profile lists or runs workflows from config.
- GPU determinism is conditional; results can change across drivers/kernels.
- Batch invariance is not guaranteed; it is measured separately.
- Strict guarantees depend on backend capabilities.
- Distributed/multiprocess inference is out of scope for now.
- docs/verification.md
- docs/examples.md
- docs/onboarding.md
- docs/flight_recorder.md
- docs/phase_diagram.md
- docs/analysis.md
- docs/experiment_planner.md
- docs/determinism_boundary.md
- docs/troubleshooting.md
- docs/vllm.md
- docs/python_api.md
- docs/versioning.md
See docs/versioning.md for compatibility guarantees.