


A performance doctor for your codebase. It finds inefficient algorithms and bottlenecks (O(n^2) loops, N+1 queries, sequential awaits, collections copied on every iteration), ranks the functions most likely to be slow, and helps your AI agent confirm each lead with profilers and growth benchmarks before touching code.
Works as a skill/plugin for 13 AI coding agents, or standalone via a dependency-free Python CLI.
Extended from codex-complexity-optimizer by Kappaemme. See CREDITS.md for full attribution and a breakdown of what this project adds.
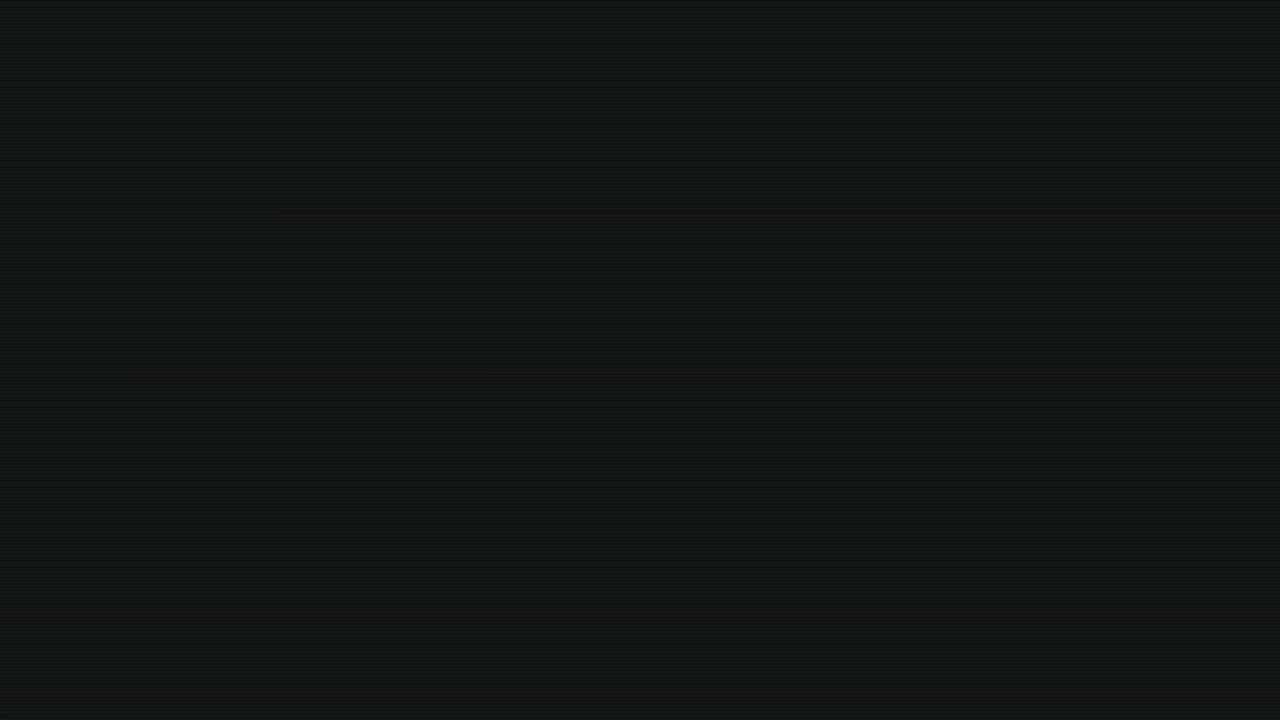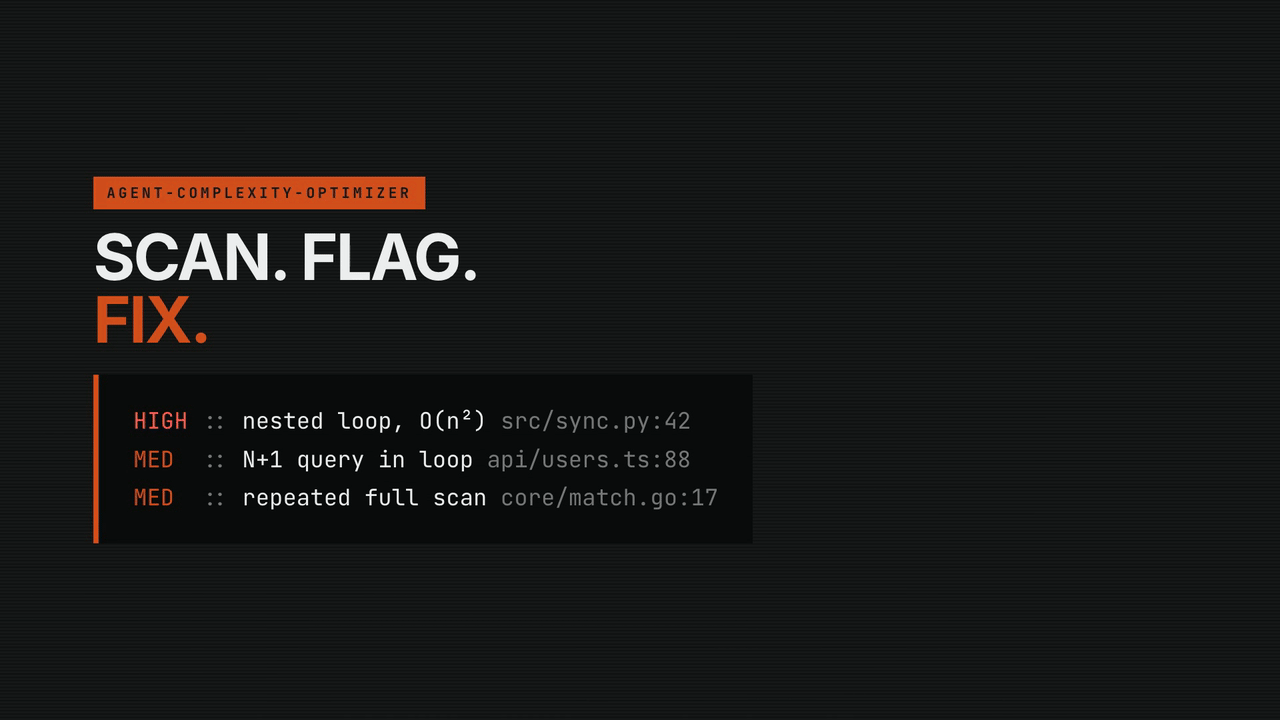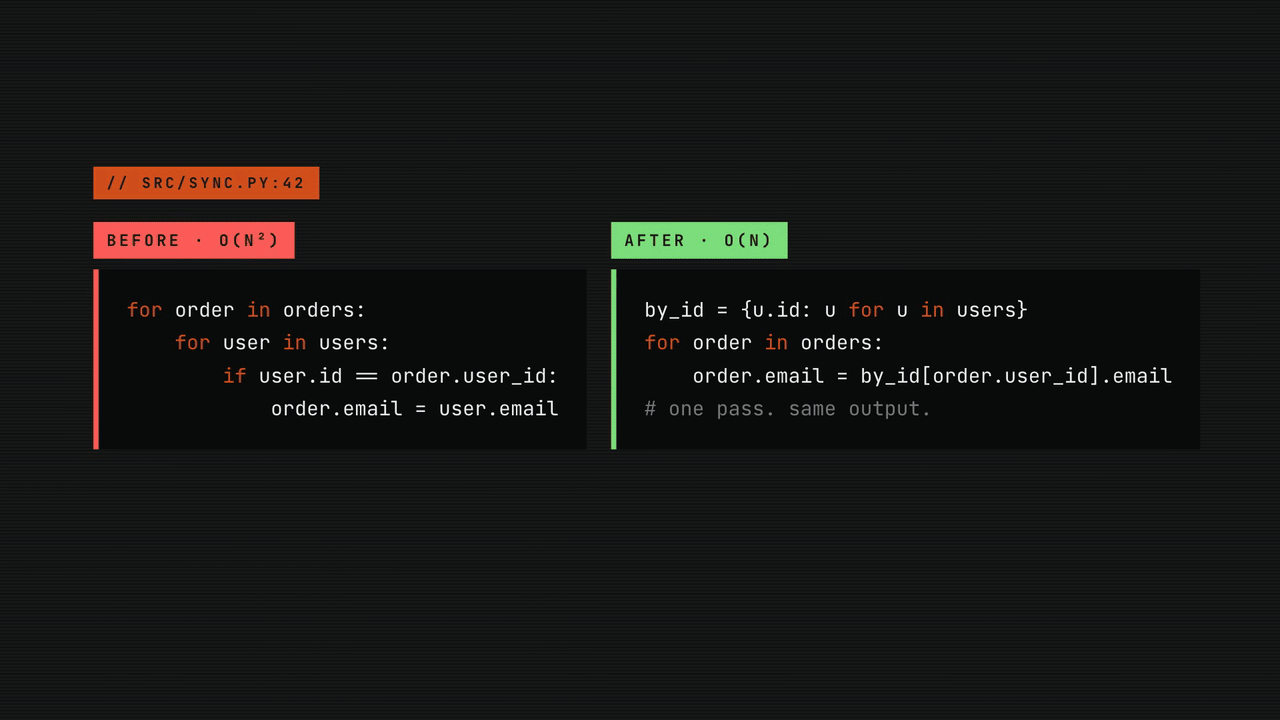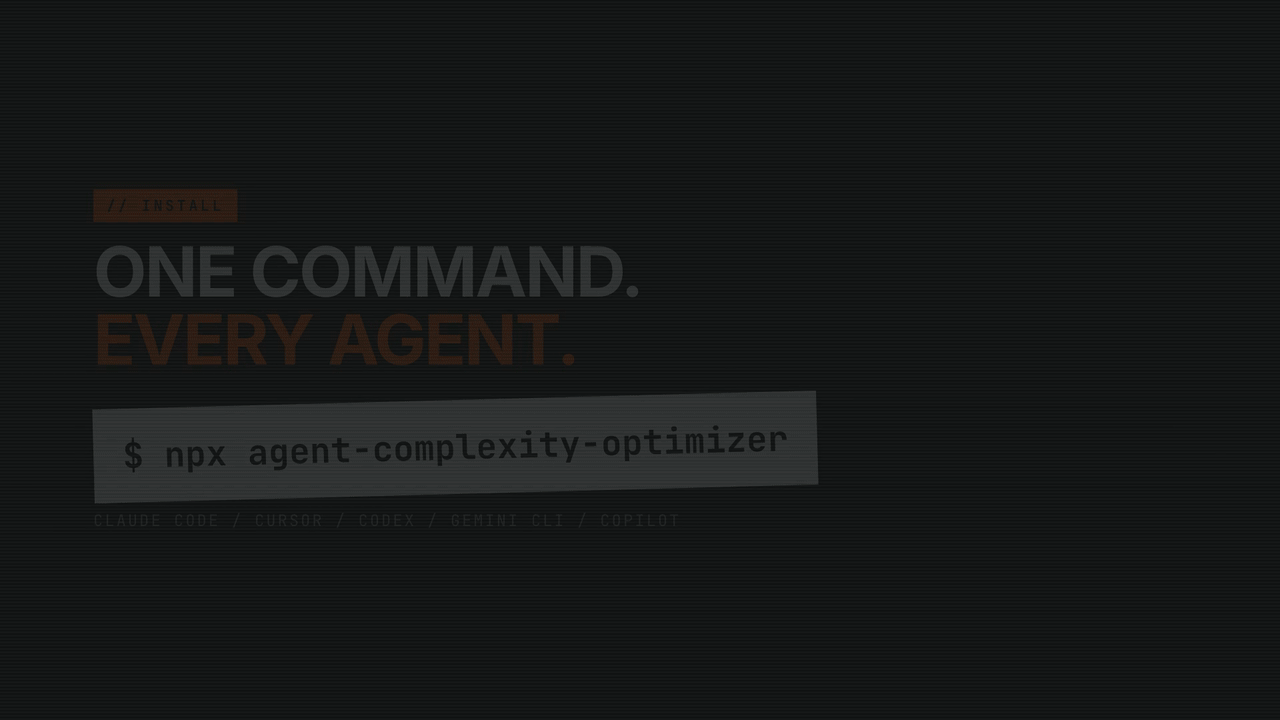
Full-quality video: demo/promo.mp4
Given this code:
def find_duplicates(users, transactions):
    duplicates = []
    for t in transactions:
        for u in users:                          # O(n*m) nested scan
            if u["id"] == t["user_id"]:
                duplicates.append(t)
    return duplicates

def get_user_orders(user_ids, db):
    results = []
    for uid in user_ids:
        order = db.query(f"SELECT * FROM orders WHERE user_id = {uid}")  # N+1
        results.append(order)
    return results
export async function notifyAll(users: User[], mailer: Mailer) {
for (const user of users) {
await mailer.send(user);
}
}
export function indexById(items: Item[]) {
return items.reduce((acc, item) => ({ ...acc, [item.id]: item }), {});
}The scanner produces (trimmed):
# Complexity Hotspots

**Density: 25.8 points per 1,000 lines** · 2 files, 21 lines scanned · 4 findings

## Top functions

| # | Function          | Location        | Score | Findings               |
|---|-------------------|-----------------|-------|------------------------|
| 1 | `find_duplicates` | `example.py:4`  | 10.0  | nested-loop            |
| 2 | `get_user_orders` | `example.py:12` | 8.0   | io-or-query-in-loop    |
| 3 | `notifyAll`       | `notify.ts:3`   | 4.2   | await-in-loop          |
| 4 | `indexById`       | `notify.ts:8`   | 3.6   | quadratic-accumulation |

## Findings

### 1. HIGH nested-loop · `example.py:4` · `find_duplicates`

    for u in users:                          # O(n*m) nested scan

- Finding: Loop over an independent collection inside another loop: O(n*m) or worse.
- Suggestion: Index the inner collection once (map/set/grouping), or use sort + two pointers / sweep line for pairwise work.
- score 10.0 · confidence high · loop depth 2
...
| Pattern | Severity | Example |
|---|---|---|
io-or-query-in-loop |
High | db.query(), repo.findOne(), fetch() per element (N+1) |
await-in-loop |
High | for (const u of users) await send(u), independent calls run one by one |
quadratic-accumulation |
High | reduce((acc, x) => ({...acc, ...})), all = all.concat(page), df = pd.concat([df, row]) |
nested-loop |
High | for a in A: for b in B over independent collections, O(n*m) |
sort-in-loop |
High | Re-sorting a growing list every iteration |
string-concat-in-loop |
Medium | s += piece in Java, Kotlin, C#, Go (immutable strings) |
list-shift-in-loop |
Medium | pop(0), shift(), remove(0) inside a loop |
dataframe-row-loop |
Medium | df.iterrows(), df.apply(f, axis=1) |
membership-in-loop |
Medium | x in list, .includes(), .contains(), .index() inside a loop |
deep-copy-in-loop |
Medium | deepcopy, JSON.parse(JSON.stringify(x)) per element |
repeated-scan |
Medium | filter() / map() builtins re-run per iteration (Python) |
regex-compile-in-loop |
Medium | new RegExp(), Pattern.compile(), regexp.MustCompile() per element |
render-derived-work |
Medium | .filter() / .sort() in a React component body without useMemo |
Precision work so leads stay trustworthy on real repos:
- Python is parsed with its AST (high confidence). It knows that
for cell in rowwalks the outer element (not a cross product), that loops overrange(3)orUPPER_CASEconstants are bounded, thatseen: set[str],self.cache = {}orusers_by_idare O(1) lookups, and thatwhilepagination, loops whose element is a chunk/batch/page (for chunk in chunks,range(0, n, batch_size)) andreturn awaitinside a loop are not per-element calls. Names are matched by whole tokens, soentriesis not a retry andwebpageis not a page. - JavaScript/TypeScript, Java, Kotlin, C#, Go, Ruby, Rust use line heuristics (low confidence) with the same ideas: strings and comments are blanked out,
Set/Map/HashSetdeclarations are tracked,repo.find({ where })is a query and not a loop, and multi-line method chains and signatures are followed. Other listed extensions (PHP, Swift, Scala, Dart, Elixir, ...) get the generic patterns only. - Noise is filtered before ranking: files ignored by
.gitignore, tests (opt in with--include-tests), and generated or minified files are skipped; migrations, seeds and scripts are ranked lower. Lines can be silenced withcomplexity: ignore (reason).
On a 1.5M-line TypeScript backend this cut the findings from 14,498 to about 4,100, with real services instead of migrations at the top, in about 8-10 s.
/plugin marketplace add sebastianbreguel/agent-complexity-optimizer
/plugin install complexity-optimizer@complexity-optimizernpx skills add sebastianbreguel/agent-complexity-optimizer -a codex -g -ynpx agent-complexity-optimizerAuto-detects installed agents (Cursor, Windsurf, Gemini CLI, Cline/Roo, Aider, OpenCode, Continue.dev, Amazon Q, Zed AI) and writes the correct config format for each. Preview with --dry-run.
GitHub Copilot reads instructions per-repository, so the installer can't set it up globally. Copy these into the repo you want to scan:
cp agents/copilot/copilot-instructions.md <your-repo>/.github/
mkdir -p <your-repo>/.github/complexity-optimizer
cp -R skills/complexity-optimizer/scripts/. <your-repo>/.github/complexity-optimizer/Python 3.10+, no dependencies:
python3 skills/complexity-optimizer/scripts/analyze_complexity.py /path/to/repo                  # markdown report
python3 skills/complexity-optimizer/scripts/analyze_complexity.py /path/to/repo --format json    # for tools
python3 skills/complexity-optimizer/scripts/analyze_complexity.py /path/to/repo --changed main # only the diff vs main| Agent | Install | Config format |
|---|---|---|
| Claude Code | marketplace / npx skills add |
SKILL.md |
| Codex (OpenAI) | npx skills add |
SKILL.md + openai.yaml |
| Pi | npm install -g |
SKILL.md (pi.skills) |
| Cursor | auto-detect | .mdc rule |
| Windsurf | auto-detect | .windsurfrules |
| GitHub Copilot | manual (per-repo .github/) |
copilot-instructions.md |
| Gemini CLI | auto-detect | GEMINI.md |
| Cline / Roo Code | auto-detect | .clinerules |
| Aider | auto-detect | CONVENTIONS.md |
| OpenCode | auto-detect | AGENTS.md |
| Continue.dev | auto-detect | Custom command YAML |
| Amazon Q | auto-detect | Rules .md |
| Zed AI | auto-detect | Assistant rules |
Agent config files under agents/ are generated from skills/complexity-optimizer/SKILL.md and a condensed template — edit the source, then run python3 scripts/sync_agents.py (CI fails on drift).
Ask your agent naturally:
Find the performance bottlenecks in this repo and give me a report.
The /orders endpoint is slow. Find out why.
Review this branch for performance regressions.
Reports are read-only by default. To apply a fix:
Implement the lowest-risk optimization from the report, run the tests, and benchmark before vs after.
The skill follows a doctor workflow: scan, triage each hotspot (how big does n get, how often does it run, is the fix safe), check the language and domain guides for what static analysis can't see, confirm with a profiler or a growth benchmark, then report. The guides cover good and bad practices for Python, JavaScript/TypeScript, React, Go, JVM, C#, Ruby, Rust, SQL/ORMs, data pipelines, and CI pipelines, plus how to measure.
measure_growth.py runs a command at growing input sizes, subtracts process startup, and fits the exponent of the median run with a 95% confidence interval, so "this is O(n^2)" becomes a measurement. It also reports how peak memory grows:
python3 skills/complexity-optimizer/scripts/measure_growth.py "python3 bench.py {n}" --sizes 4000 8000 16000 32000 n seconds peak MB local exp
4000 0.0336 16.0 —
8000 0.1032 16.3 —
16000 0.3678 16.9 1.95
32000 1.4459 18.2 2.01
Startup (n=0): 0.0106 s and 15.7 MB, subtracted before fitting.
Time exponent: 1.98 (95% CI 1.90 to 2.00, R² 1.00) -> O(n^2) (from 3 of 4 sizes)
Memory: under 10 MB above startup at most sizes, too little to fit.
When the interval spans more than one class it answers "inconclusive" and lists them, instead of guessing. Memory growth under 10 MB above startup is too small to fit, as here.
Each rule's weight is a judgment call until real verdicts measure its precision. After triaging or fixing a finding, record whether it was real; the report gives precision per rule and language and flags noisy rules:
python3 skills/complexity-optimizer/scripts/verdicts.py add ~/.complexity-optimizer/verdicts/shop.jsonl "src/orders.py::load_all::io-or-query-in-loop" confirmed
python3 skills/complexity-optimizer/scripts/verdicts.py report ~/.complexity-optimizer/verdicts/*.jsonlSave today's findings as a baseline, then fail only when a change adds new ones (--changed alone selects whole files, so combine it with a baseline from main to review a branch):
python3 analyze_complexity.py . --write-baseline complexity-baseline.json    # once, commit the file
python3 analyze_complexity.py . --baseline complexity-baseline.json --fail-on high
Findings are matched by file, function and pattern (not line number), so unrelated edits don't make old findings look new. The report also shows how many baseline findings were fixed.
Every rule is measured against a labeled corpus in tests/cases/: source files in each language where lines carry expect: <pattern> (must be reported), todo: <pattern> (known miss), or todo-fp: <pattern> (known false positive). Every other reported line counts as a false positive.
python3 scripts/evaluate_rules.pyrule TP FP FN precision recall
await-in-loop 2 0 0 100% 100%
io-or-query-in-loop 9 0 0 100% 100%
nested-loop 14 0 0 100% 100%
...
Found a false positive or a missed bottleneck in a real repo? Add a small case reproducing it to tests/cases/<language>/, run the evaluator, fix the rule, and pytest keeps it from regressing.
The original project supported Codex only. This fork extends it to 13 agents and adds:
- Universal installer — auto-detects agents and writes native config formats
- Claude Code marketplace — first-class plugin support
- Ranked hotspots — findings scored by pattern, loop depth and confidence, grouped by function, with a density that tracks progress
- More patterns — sequential awaits, quadratic accumulation, string building, front removal, pandas row loops, deep copies, regex compiles
- Precision on real code — Python AST data-flow hints, type and naming heuristics,
.gitignore/test/generated filtering - Diff and CI modes —
--changed, baselines,--fail-on - Measurement —
measure_growth.py(time and memory exponents with confidence intervals), profiling and benchmarking guides per language - Verdicts —
verdicts.pyrecords whether findings were real and reports precision per rule - A labeled rule corpus — per-rule precision/recall to keep improving the scanner
MIT