
Yggdrasil AI is a full-stack AI workspace built with React, FastAPI, and Azure AI Foundry, designed to go beyond a traditional chatbot. It combines persistent conversation memory, intelligent request routing, semantic caching, document understanding, and extensible AI tooling into a production-oriented architecture.
The project focuses on building an AI application the way modern AI products are built: fast, modular, provider-agnostic, and easy to extend.
Switch to latest version in branches to see latest development.
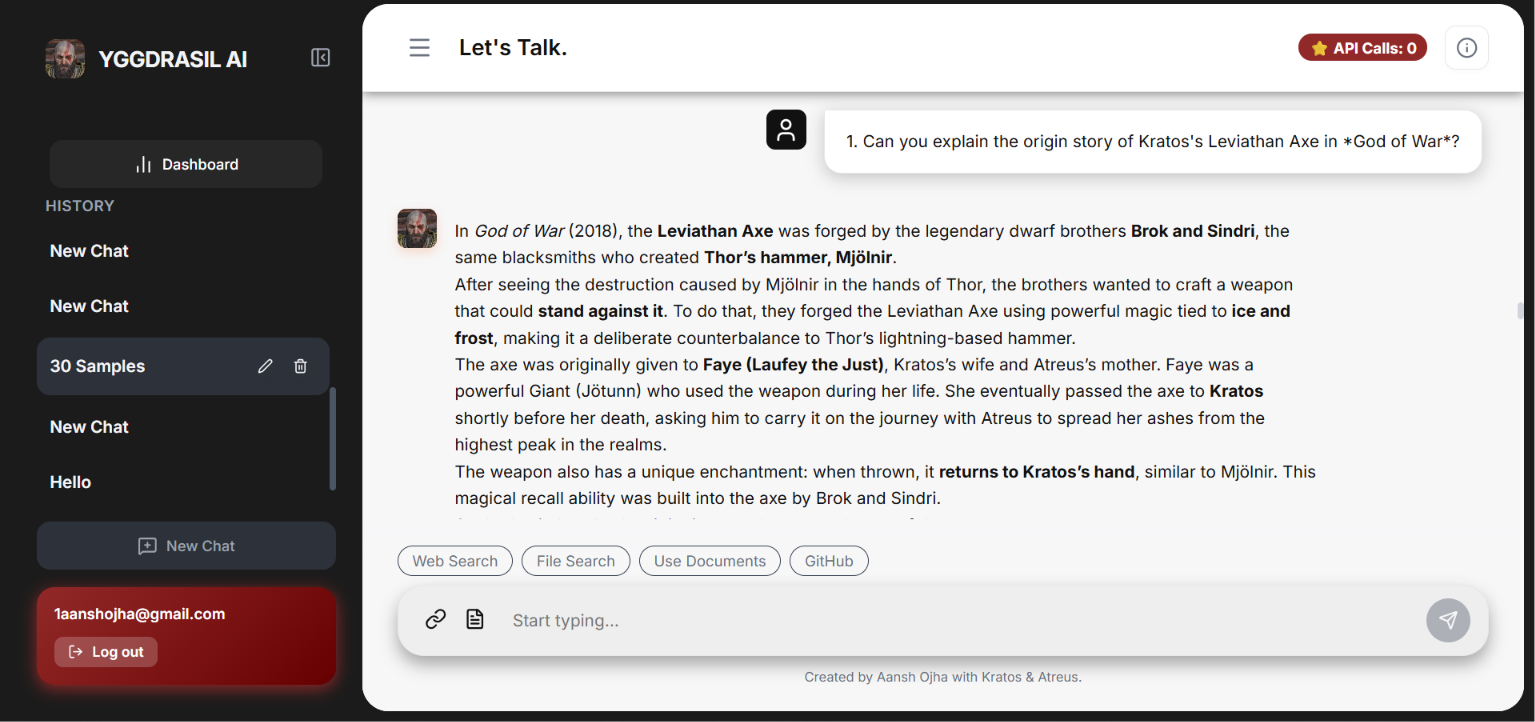
Unlike most AI chat applications that simply forward prompts to an LLM, Yggdrasil introduces an architecture that optimizes latency, cost, and extensibility.
Conversations are stored in the database instead of relying on provider-managed memory, giving complete control over context management.
Users can:
- Continue previous conversations
- Upload documents and images
- Build long-term AI workspaces
- Remain independent of any single LLM provider
Instead of using one generic prompt for every request, Yggdrasil routes requests to specialized skills.
Current architecture supports specialized workflows such as:
- General Chat
- Resume Review
- Code Review
- Interview Coach
- Document Analysis
Adding a new capability only requires creating a new skill instead of rewriting the entire application.
To reduce latency and API costs, Yggdrasil implements a two-stage intelligent caching pipeline.
Stage 1
- Redis + RediSearch vector similarity search
Stage 2
- BM25 lexical re-ranking for precision
This significantly improves cache accuracy compared to vector search alone while reducing unnecessary LLM calls.
Responses are streamed token-by-token, producing a responsive ChatGPT-like experience instead of waiting for the complete generation.
Supports the Model Context Protocol (MCP), allowing AI models to interact with external tools.
Current implementation includes GitHub MCP, enabling the assistant to work with repositories through natural language while keeping the architecture open for additional MCP servers.
The project is intentionally modular.
Future integrations can include:
- Additional LLM providers
- New AI skills
- More MCP servers
- Agent workflows
- Custom enterprise integrations
The architecture is designed so new functionality can be added with minimal changes to existing code.
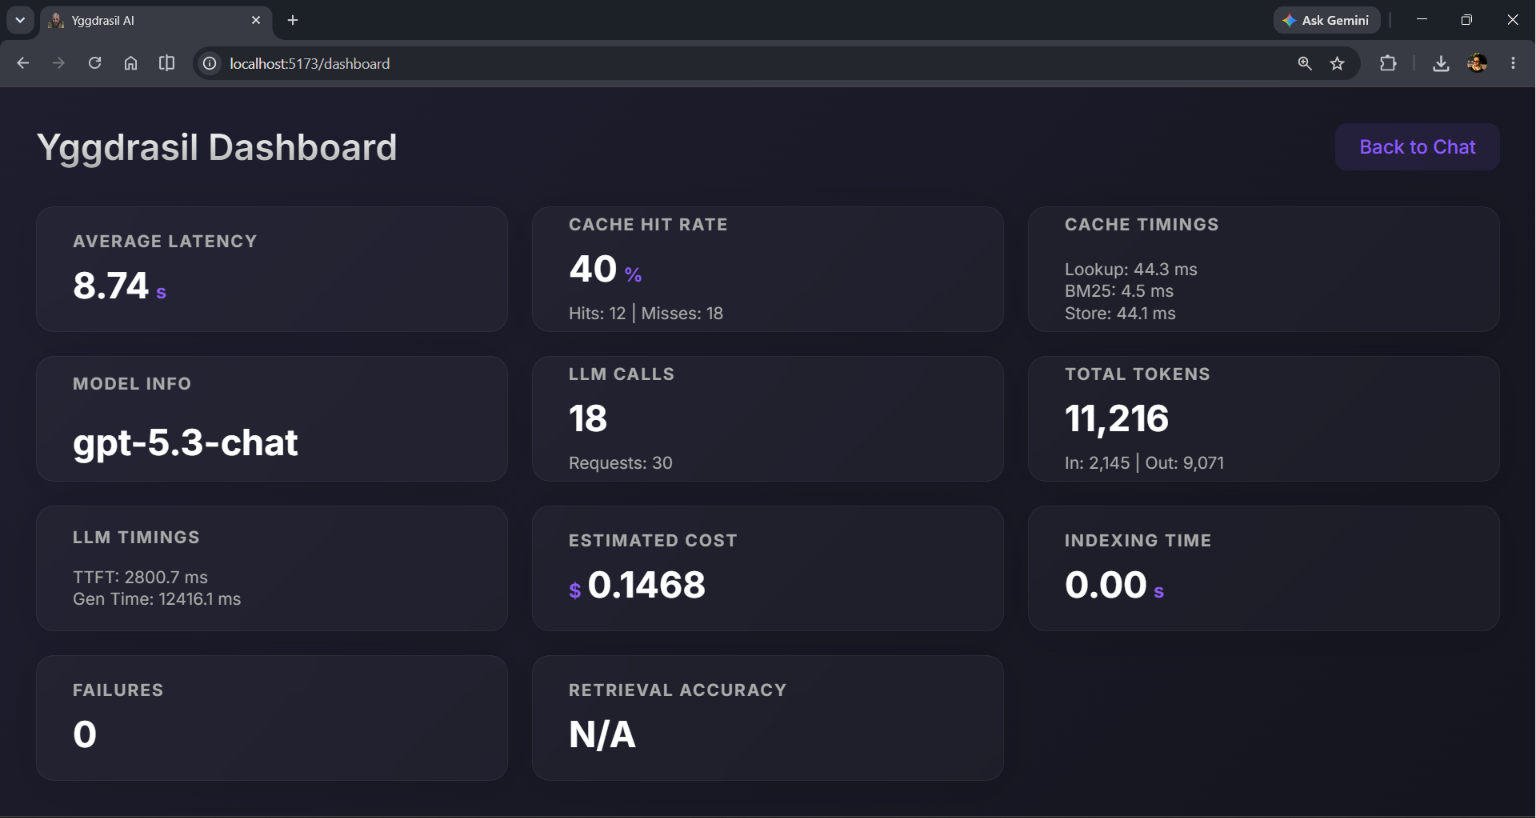
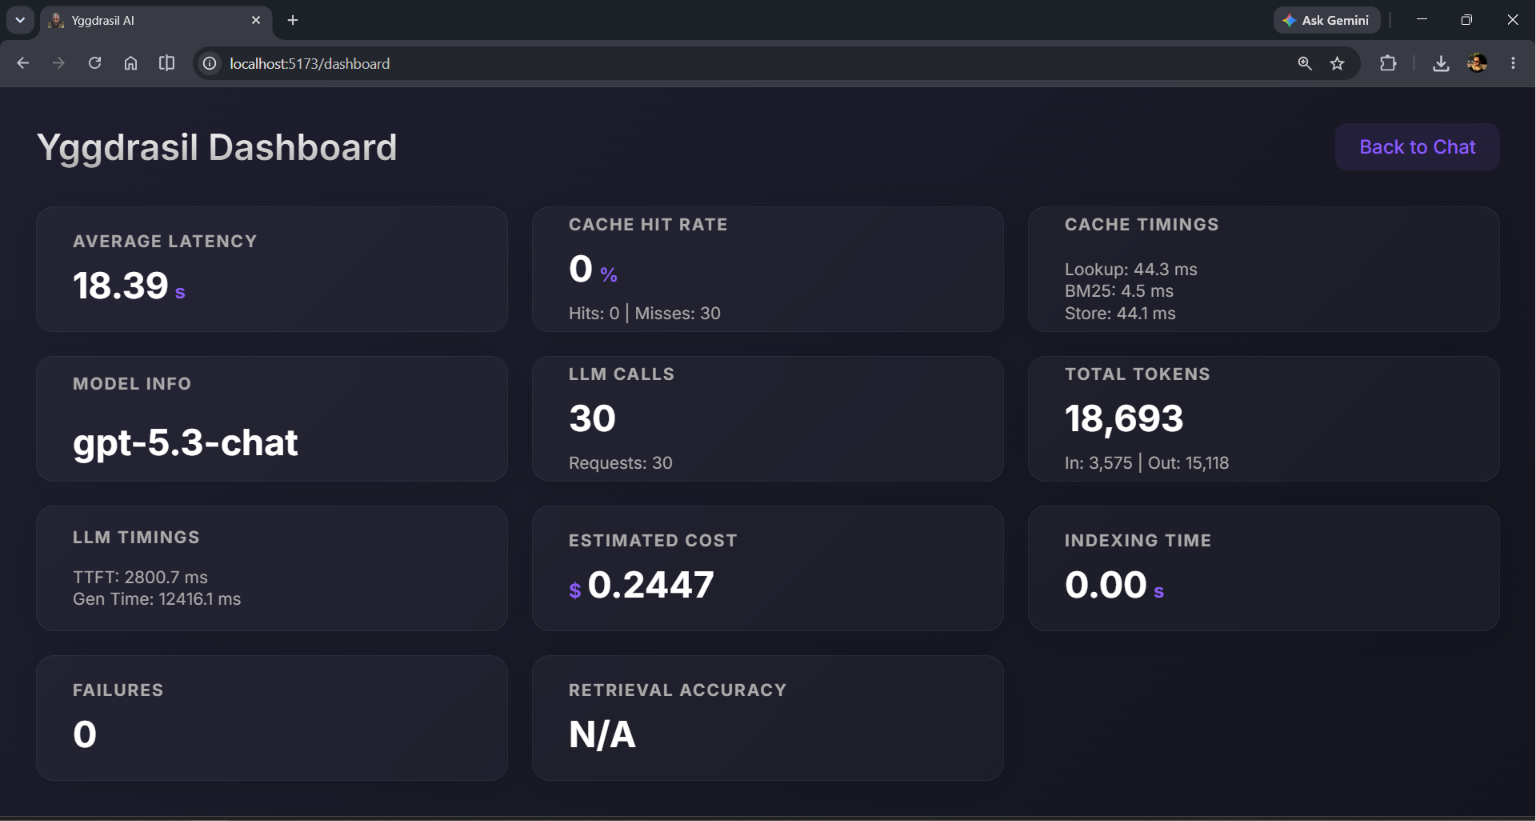
Tracks application performance including:
- Time to First Token (TTFT)
- Total generation latency
- Redis lookup latency
- BM25 re-ranking latency
- Cache hit rate
- Token usage
- Estimated API cost
- Failure rate
- FastAPI backend with asynchronous architecture
- PostgreSQL / SQLite using SQLAlchemy
- Redis semantic caching with RediSearch
- Dense Vector Search + BM25 re-ranking
- Streaming LLM responses
- Persistent chat history
- File uploads with Retrieval-Augmented Generation (RAG)
- Azure OpenAI / OpenAI compatible provider abstraction
- GitHub MCP integration
- Background task processing
- Real-time telemetry and performance metrics
- React + TypeScript
- Vite
- Responsive chat interface
- Conversation history
- File uploads
- Real-time streamed responses
Instead of using OpenAI's Responses API conversation storage, Yggdrasil stores messages in its own database.
This approach provides:
- Complete ownership of conversation history
- Easier migration to Anthropic, Gemini, local models, or future providers
- Full control over memory management
- Better long-term maintainability
Although provider-managed memory requires less code, database-backed conversations make the overall architecture significantly more flexible.
.art .bat .brf .c .cls .css .csv .diff .doc .docx .dot .eml
.es .h .hs .htm .html .hwp .hwpx .ics .ifb .java .js .json
.keynote .ksh .ltx .mail .markdown .md .mht .mhtml .mjs
.nws .odt .pages .patch .pdf .pl .pm .pot .ppa .pps .ppt
.pptx .pwz .py .rst .rtf .scala .sh .shtml .srt .sty .svg
.svgz .tex .text .txt .tsv .vcf .vtt .wiz .xla .xlb .xlc
.xlm .xls .xlsx .xlt .xlw .xml .yaml .yml
.png
.jpg
.jpeg
.webp
.gif
- React 18
- TypeScript
- Vite
- Context API
- Python
- FastAPI
- SQLAlchemy
- PostgreSQL
- SQLite
- Redis
- RediSearch
- Azure AI Foundry / OpenAI
- Model Context Protocol (MCP)
- Node.js 18+
- Python 3.10+
- Docker
- Git
git clone https://github.com/AanshOjha/Yggdrasil-AI.git
cd Yggdrasil-AIcd backend
python -m venv venv
# Windows
venv\Scripts\activate
pip install -r requirements.txtCreate a .env
AZURE_ENDPOINT=
AZURE_TOKEN_PROVIDER=
DEPLOYMENT_NAME=
SECRET_KEY=
DATABASE_URL=
Start PostgreSQL
docker-compose up -dRun the backend
uvicorn app.main:app --reloadBackend:
http://localhost:8000
API Documentation:
http://localhost:8000/docs
cd frontend

npm install

npm run dev
Frontend:
http://localhost:5173
- Multi-agent workflows
- More MCP servers
- Voice conversations
- Additional LLM providers
- Advanced analytics
- Team workspaces
- Plugin ecosystem
Licensed under the MIT License.